1Step 01
Describe your image
Write a prompt describing the subject, style, and details you want Qwen to generate.
Write your prompt hereStudio shot of the product on a clean neutral background


Direct the scene your way. Create visuals with intentional angles, depth, and style
Combining both gives the best results
Run prompts, evaluate outputs, and prepare OpenVINO-friendly workflows in one place—so teams can move from experiments to deployable results with clear checks and repeatable runs.
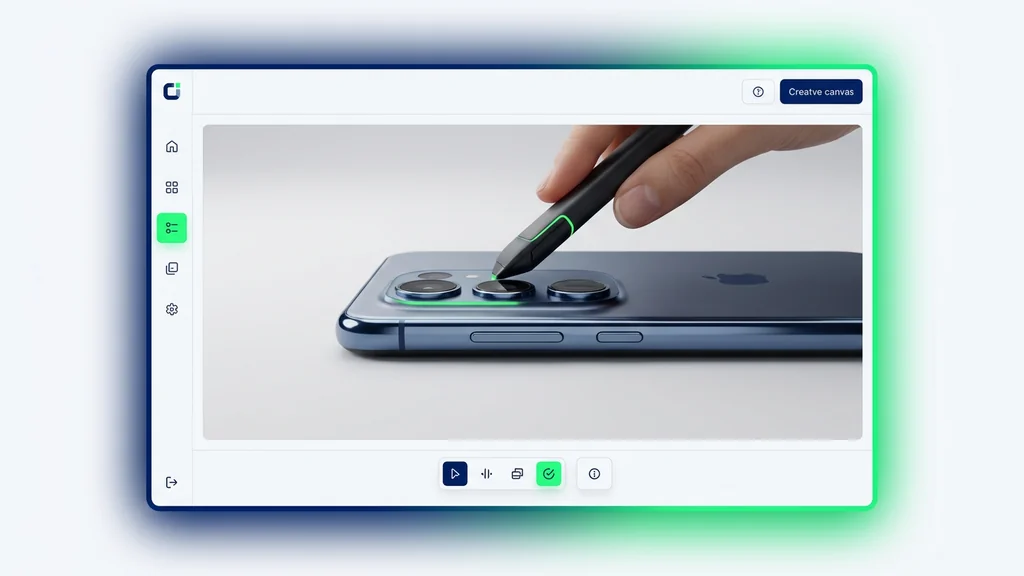
From a written idea to a finished image — no setup, no plugins, no Discord.
Write a prompt describing the subject, style, and details you want Qwen to generate.
Pick your aspect ratio and how many variations to generate in one run.
Click generate and wait a few moments. Qwen creates your images. Download them, or refine your prompt and run again.
In Cleep AI, a team starts by submitting a prompt set or a small JSON suite of test cases to establish a baseline. Next, they run the same inputs across variants (for example Qwen2.5-Turbo for speed or Qwen2.5-14B for heavier reasoning) and capture outputs in a consistent format. Finally, they export the winning prompt template and evaluation notes to guide an OpenVINO deployment pass with fewer surprises.
Product teams use the model to draft and normalize customer-facing content, then enforce structure like JSON fields for downstream systems. Engineering teams use it for code explanations, log summarization, and requirement-to-task breakdowns that can be replayed against new builds. For voice workflows, Qwen-Audio-style tasks can be evaluated by attaching short clips and checking whether transcripts and answers stay aligned to the audio.
Cleep AI helps teams review outputs with a repeatable checklist: format validity (JSON parses), instruction adherence, and citation/grounding when sources are provided. For multi-turn tasks, they verify that the model keeps constraints stable across follow-ups and doesn’t drift in schema. When audio is involved, they spot-check timestamps, named entities, and whether the answer reflects what was actually said.
Cleep AI is built for running the same evaluation inputs repeatedly, so teams can track changes when they switch variants like Qwen2.5-32B or experiment with Qwen’s QwQ-32B-Preview. It keeps prompts, test cases, and outputs together so decisions are based on evidence rather than one-off demos. That makes it easier to hand off a stable prompt spec to engineering for OpenVINO packaging and runtime testing.
Start with a small set of prompts that represent your real workload, then run them as a batch to see where outputs break format or miss constraints. Save the best-performing prompt template and share it with your team as the single source of truth. When you’re ready to deploy, use the saved evaluation notes as a practical checklist for OpenVINO runtime validation.